A fun case study on putting the hype to a real test. Lucia van den Brink ran the experiment on actual data.
Metrics
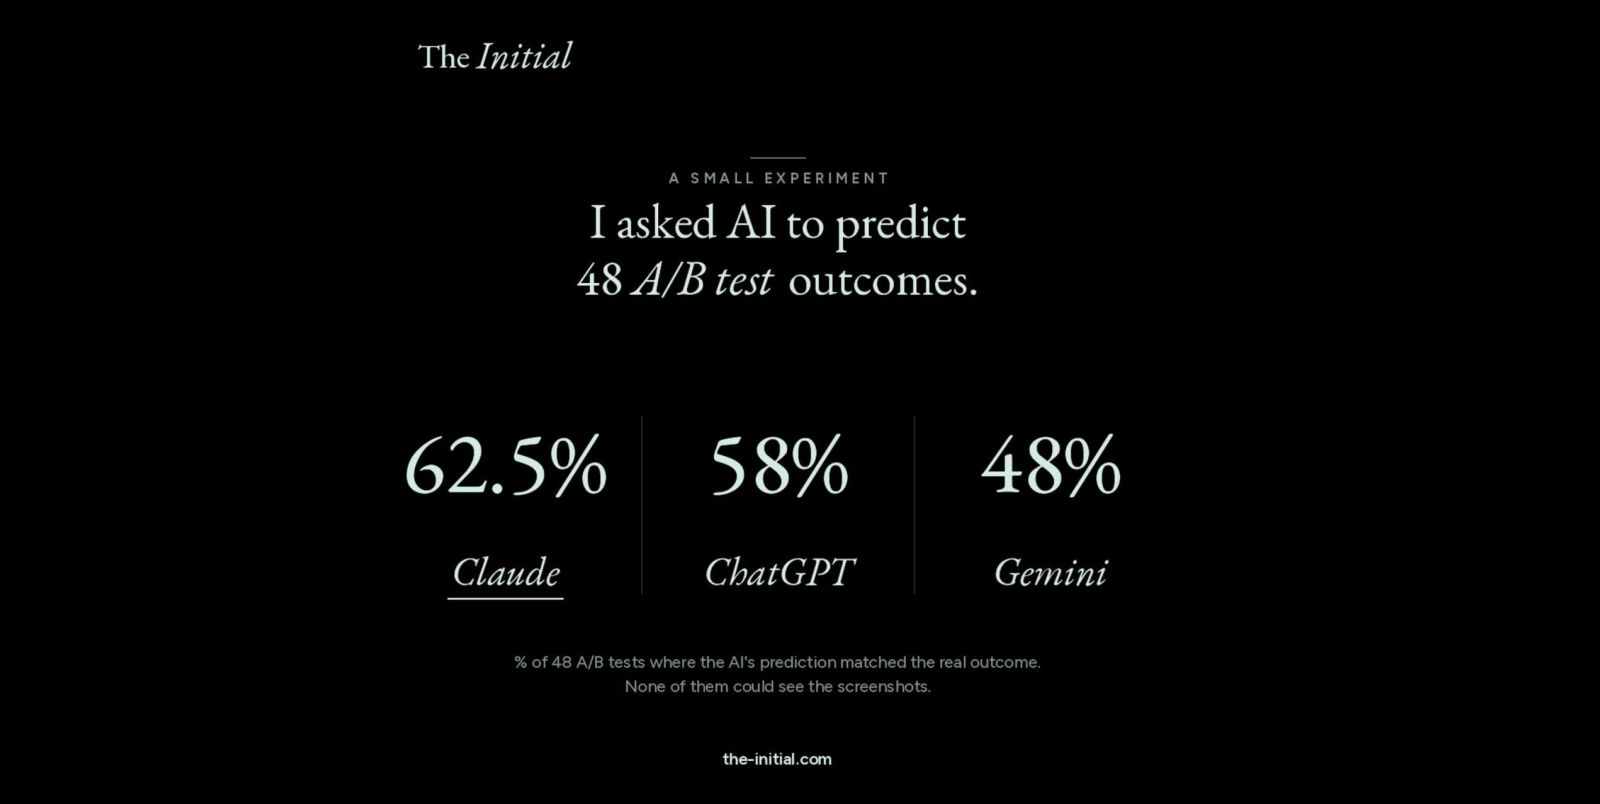
- 48 tests in the dataset
- Claude – 62.5% correct predictions
- ChatGPT – 58%
- Gemini – 48%
- Confidence interval: 35.9–64.1%
What was done?
Data exported from Airtable – hypotheses, prioritization, research. Three models were asked to predict the winner. Design screenshots were included as links – none of the models could open them.
What happened?
All three models predicted blindly. Claude had the best result, but every number falls within statistical noise. You’d get the same accuracy flipping a coin.
The takeaway?
With a sample of 48 tests, the difference between models is meaningless. To make any real claim about predictive power – you need a dataset many times larger and actual access to the designs.
Want a stronger data analyst role or a raise? Grab the FREE Product Analyst Playbook and get the exact roadmap to your next offer.